DynamoDB Migrations Without Downtime
Coming from SQL, a migration is an ALTER TABLE, and some of them (a type
change, a volatile default) lock the table while they rewrite every row.
DynamoDB has no schema to alter: adding an attribute or a new entity type is
just a write.
The hard part is the access pattern the new data has to serve, and reshaping live data to serve it without a stop-the-world rewrite.
How do you migrate a DynamoDB table without downtime?
DynamoDB has no ALTER TABLE, so migrations never lock the table. You add attributes and new sort-key shapes with ordinary writes, and add a GSI online with UpdateTable; the table's own key schema can't change. Then reshape live data incrementally: backfill old items lazily on read or with a throttled sweep, and dual-write during the transition.
- A new GSI skips old items until you write its key attributes onto them. The online build copies existing items, but it can't invent attributes.
- Guard every backfill write with
attribute_exists(PK), or an update can resurrect an item deleted mid-sweep. - Keys are immutable. Moving an item to a new
PK/SKis a copy and a delete, best done in one transaction per item. - Finish with a count: a
Scanfor items still missing the new attributes should come back at 0 before readers switch over.
Frame it as an access pattern, not a column
Say you run a SaaS workspace product on one table. Items use PK = "WS#<id>"
and SK overloaded per entity:
| PK | SK | attributes |
|---|---|---|
| WS#a91 | META | name, tier |
| WS#a91 | DOC#2026-04-01#x7 | title, author, body |
| WS#a91 | DOC#2026-04-02#k2 | title, author, body |
Now product wants comments on documents, plus a new read: "list every comment a member wrote across the workspace, newest first." That last clause is the migration. A new entity type alone is trivial; serving a query the current keys can't answer is the work.
Add the new entity type first
Comments are just new items in the same partition, with no new table:
| PK | SK | attributes |
|---|---|---|
| WS#a91 | CMT#2026-04-01#x7#01HZ... | author, text, createdAt |
A Query on PK = "WS#a91" with SK begins_with "CMT#2026-04-01#x7#" lists
one document's comments. See item collections and overloaded keys
for why the same partition holds both.
Pick a sort-key prefix that no existing query matches.
Had comments used
DOC#2026-04-01#x7#CMT#…, every existing begins_with(SK, "DOC#") reader would
start returning comments mixed in with documents on day one. If you must share
a prefix, make every existing reader filter on an entity-type attribute first.
The new query needs a GSI
"All comments by a member, newest first" can't be served by the base table:
the comment's author is neither the PK nor an SK prefix. That's a new index,
and choosing it is its own decision; see GSI vs LSI.
An LSI must exist at table creation, so on a live table a GSI is your only option.
Add a generic GSI1 and write its key attributes on new comment items,
derived from author and createdAt and scoped to the workspace:
| GSI1PK | GSI1SK |
|---|---|
| WS#a91#MEMBER#u44 | 2026-04-02T09:15:00Z |
Query GSI1 WHERE GSI1PK = "WS#a91#MEMBER#u44" with ScanIndexForward = false
gives newest-first comments per member in that workspace.
Build the index online
UpdateTable adds a GSI to a live table with no downtime. DynamoDB backfills
existing items into the index in the background; the index reports CREATING
(Backfilling: true once it starts copying) until done, then flips to ACTIVE
(Managing GSIs).
Two traps here. First, a GSI whose new key is skewed can throttle base-table writes while it builds. AWS's advice:
- Add it when your application drives the least traffic, and turn on Contributor Insights for the table and the index to see the key distribution.
- Watch
OnlineIndexPercentageProgress, and the base table'sWriteThrottleEventsandThrottledRequests. - "Be prepared to cancel the index creation." While it's backfilling you can
delete it:
aws dynamodb update-table --table-name Workspace --global-secondary-index-updates '[{"Delete":{"IndexName":"GSI1"}}]'.
The mechanism is in why a GSI throttles its base table.
Second, the index is eventually consistent even
after it goes ACTIVE, and it rejects ConsistentRead: true.
When a user must
see the comment they just wrote, read it from the base table with a strongly
consistent GetItem, or show it from the write response. See
why GSIs are eventually consistent.
Backfill the old items
The GSI only indexes items that have GSI1PK/GSI1SK. Your pre-migration
comments, written before the attribute existed, never appear, even after the
build completes. You have to add the values.
Two strategies:
| Strategy | How it works | Use when |
|---|---|---|
| Lazy | On read of an old item, write back the new attributes | Old items are read often; end with a sweep |
| Sweep | A paginated Scan updates every old item once | You need the GSI complete by a deadline |
Lazy alone never finishes: an old comment nobody reads never gains GSI1PK.
Use it to spread the cost, then run the sweep before readers switch to GSI1.
For the sweep, page through with Scan (split it with Segment /
TotalSegments for a parallel scan on a large
table) and send one guarded UpdateItem per old comment:
# UpdateItem
Key                  PK = "WS#a91", SK = "CMT#2026-04-01#x7#01HZA"
UpdateExpression     SET GSI1PK = :pk, GSI1SK = :sk
ConditionExpression  attribute_exists(PK) AND attribute_not_exists(GSI1PK)
Values               :pk = "WS#a91#MEMBER#u44", :sk = "2026-04-01T10:00:00Z"
Both halves of the condition matter. UpdateItem creates the item if it's
missing, so without attribute_exists(PK) a comment deleted after your Scan
page comes back as a ghost holding only keys and GSI attributes.
attribute_not_exists(GSI1PK) stops the sweep from overwriting a value the
dual-write path already set. Treat a ConditionalCheckFailedException as "skip".
The DynamoDB Expression Builder builds the
same request with its name and value maps.
Dual-write through the transition
Until every old item carries the new attributes, two shapes coexist. The write
path must set GSI1PK/GSI1SK on every write, new comments and any update
to an old one, so the gap only shrinks.
Before you point readers at GSI1, prove the gap is closed. Run a Scan with
Select: COUNT and
FilterExpression: begins_with(SK, :cmt) AND attribute_not_exists(GSI1PK), and
sum Count across every page.
It costs a full-table read; switch only at 0.


Pitfalls
- Adding the attribute ≠ backfilled. Verify with the count above before you trust the query.
- Changing a key in place is a rewrite. You can't mutate an item's
PK/SK. Move each item in oneTransactWriteItems: aPutof the new key guarded byattribute_not_exists(PK)and aDeleteof the old key guarded byattribute_exists(PK). Readers check both keys until the move finishes. - No transactional cutover. There's no moment where the whole table flips. Design every step to be safe while both shapes are live.
Next steps
Sanity-check the new keys and overloaded collections in single-table design.
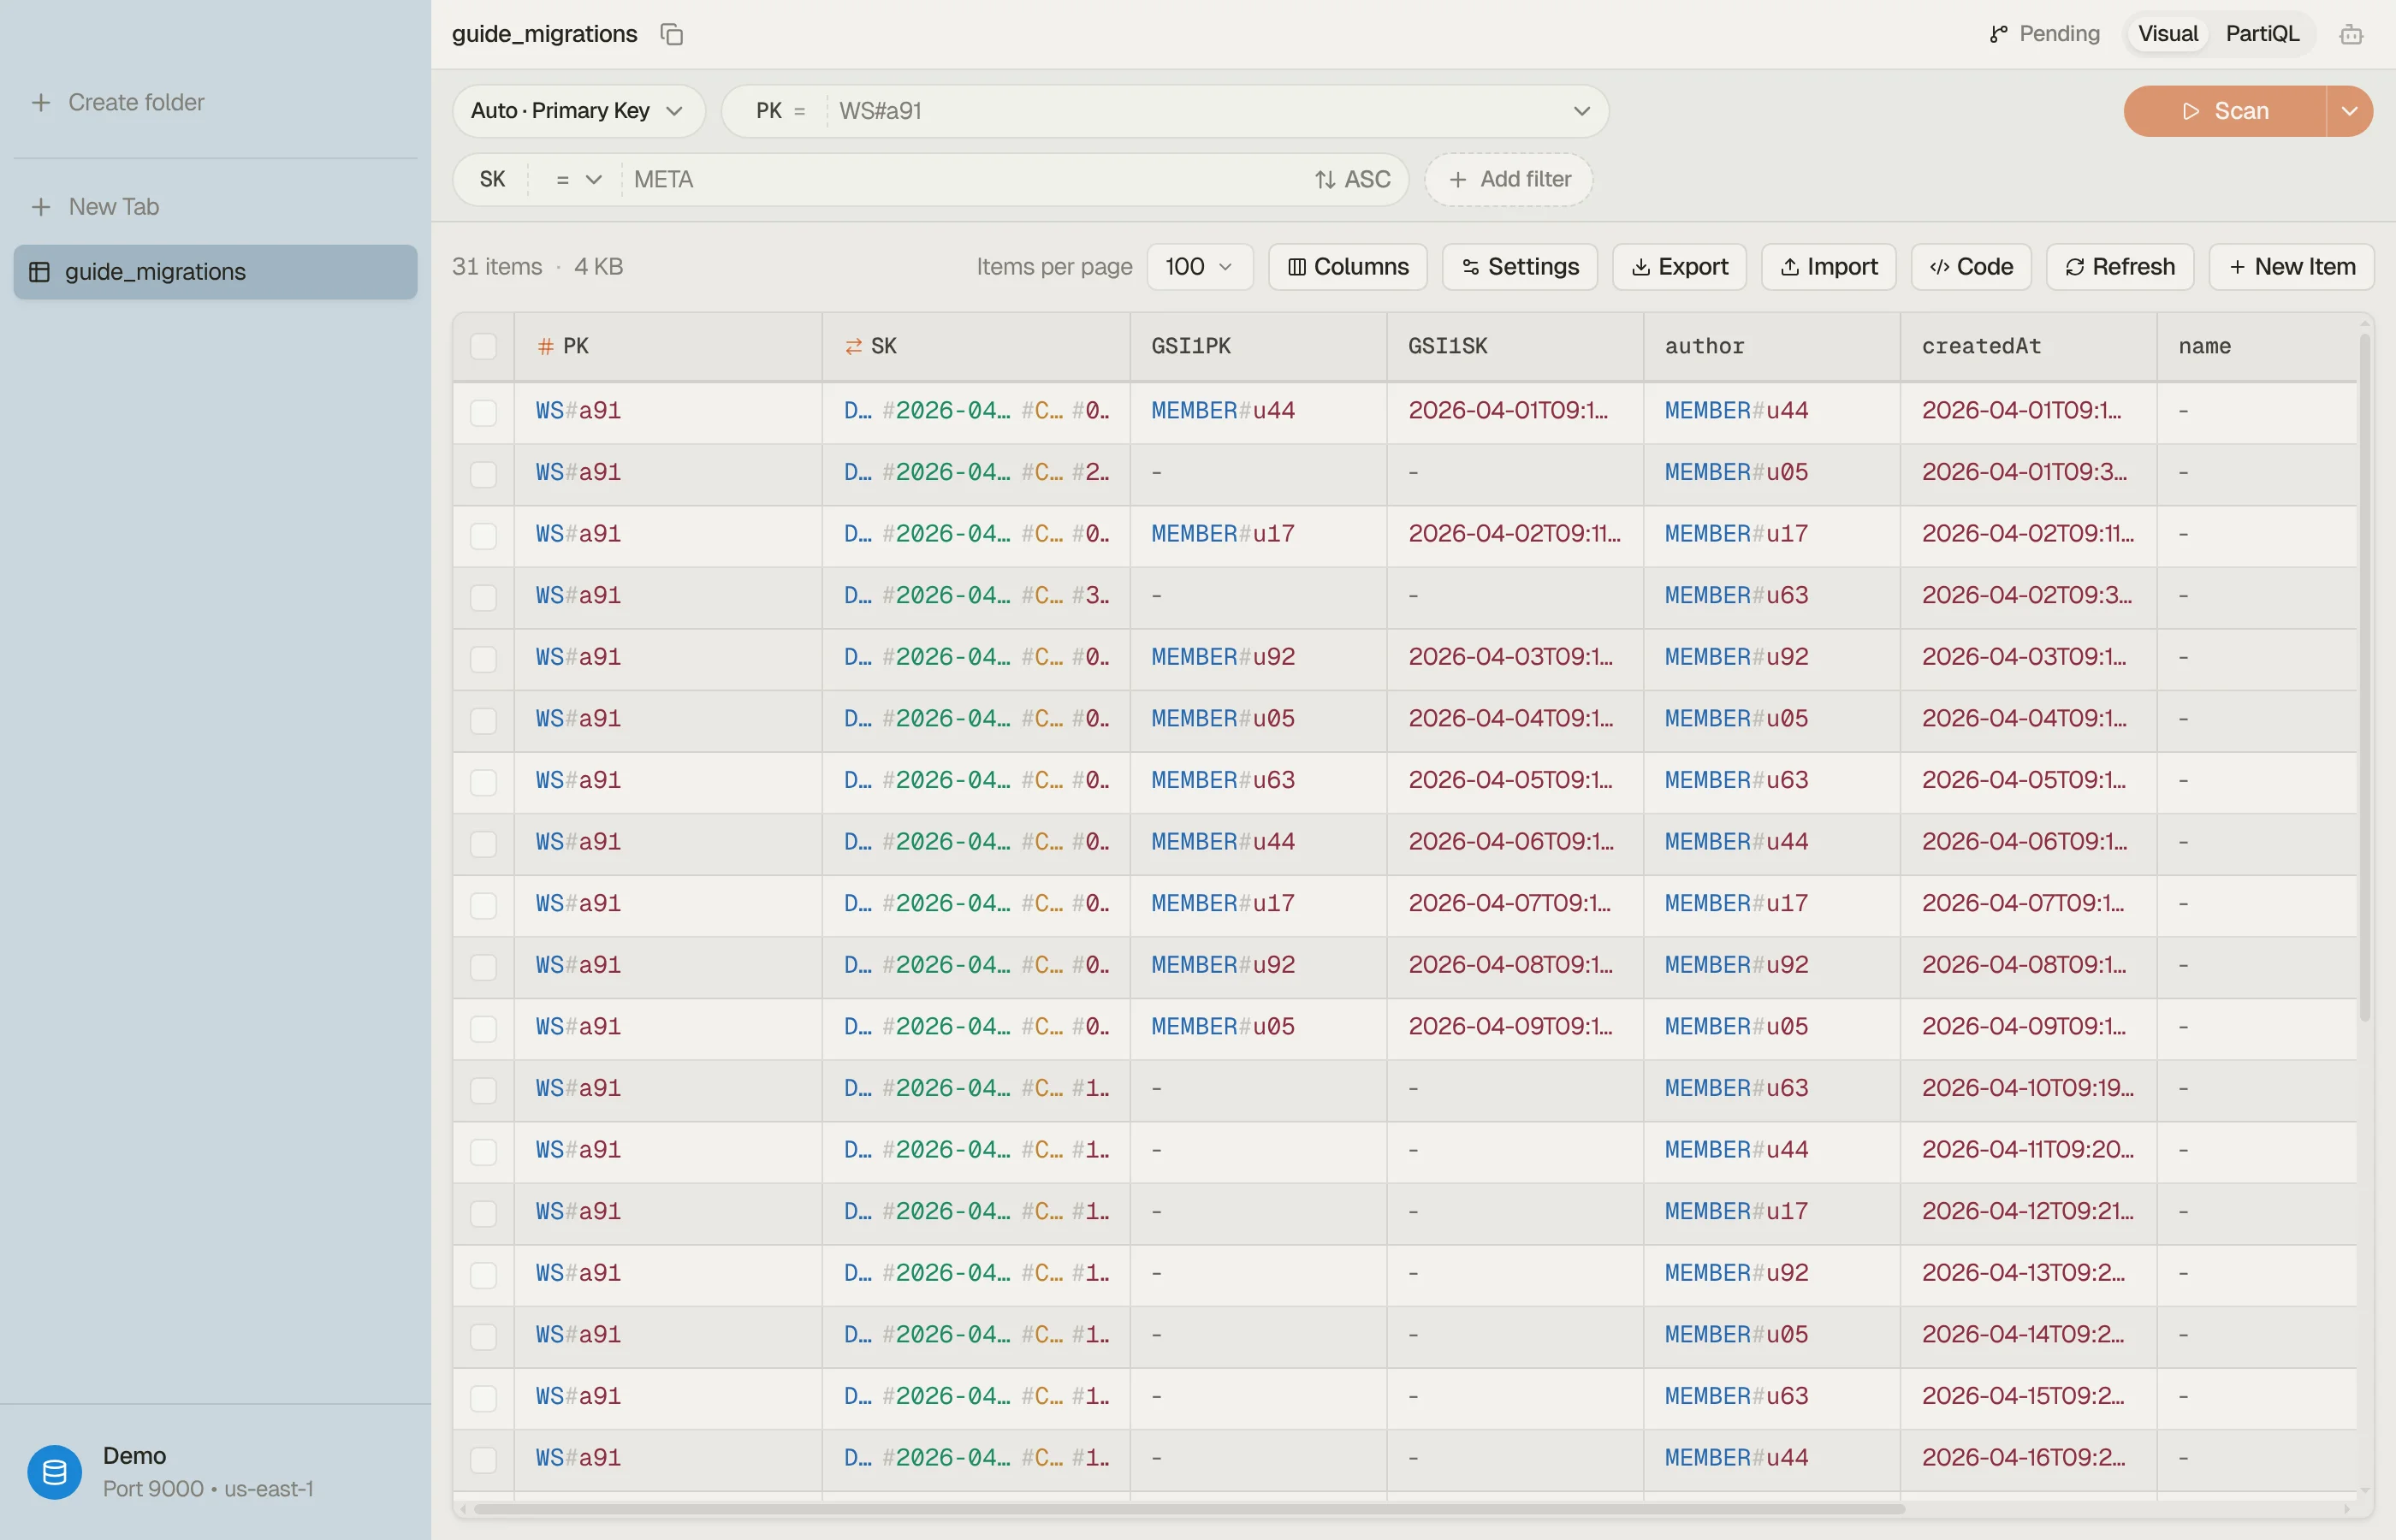
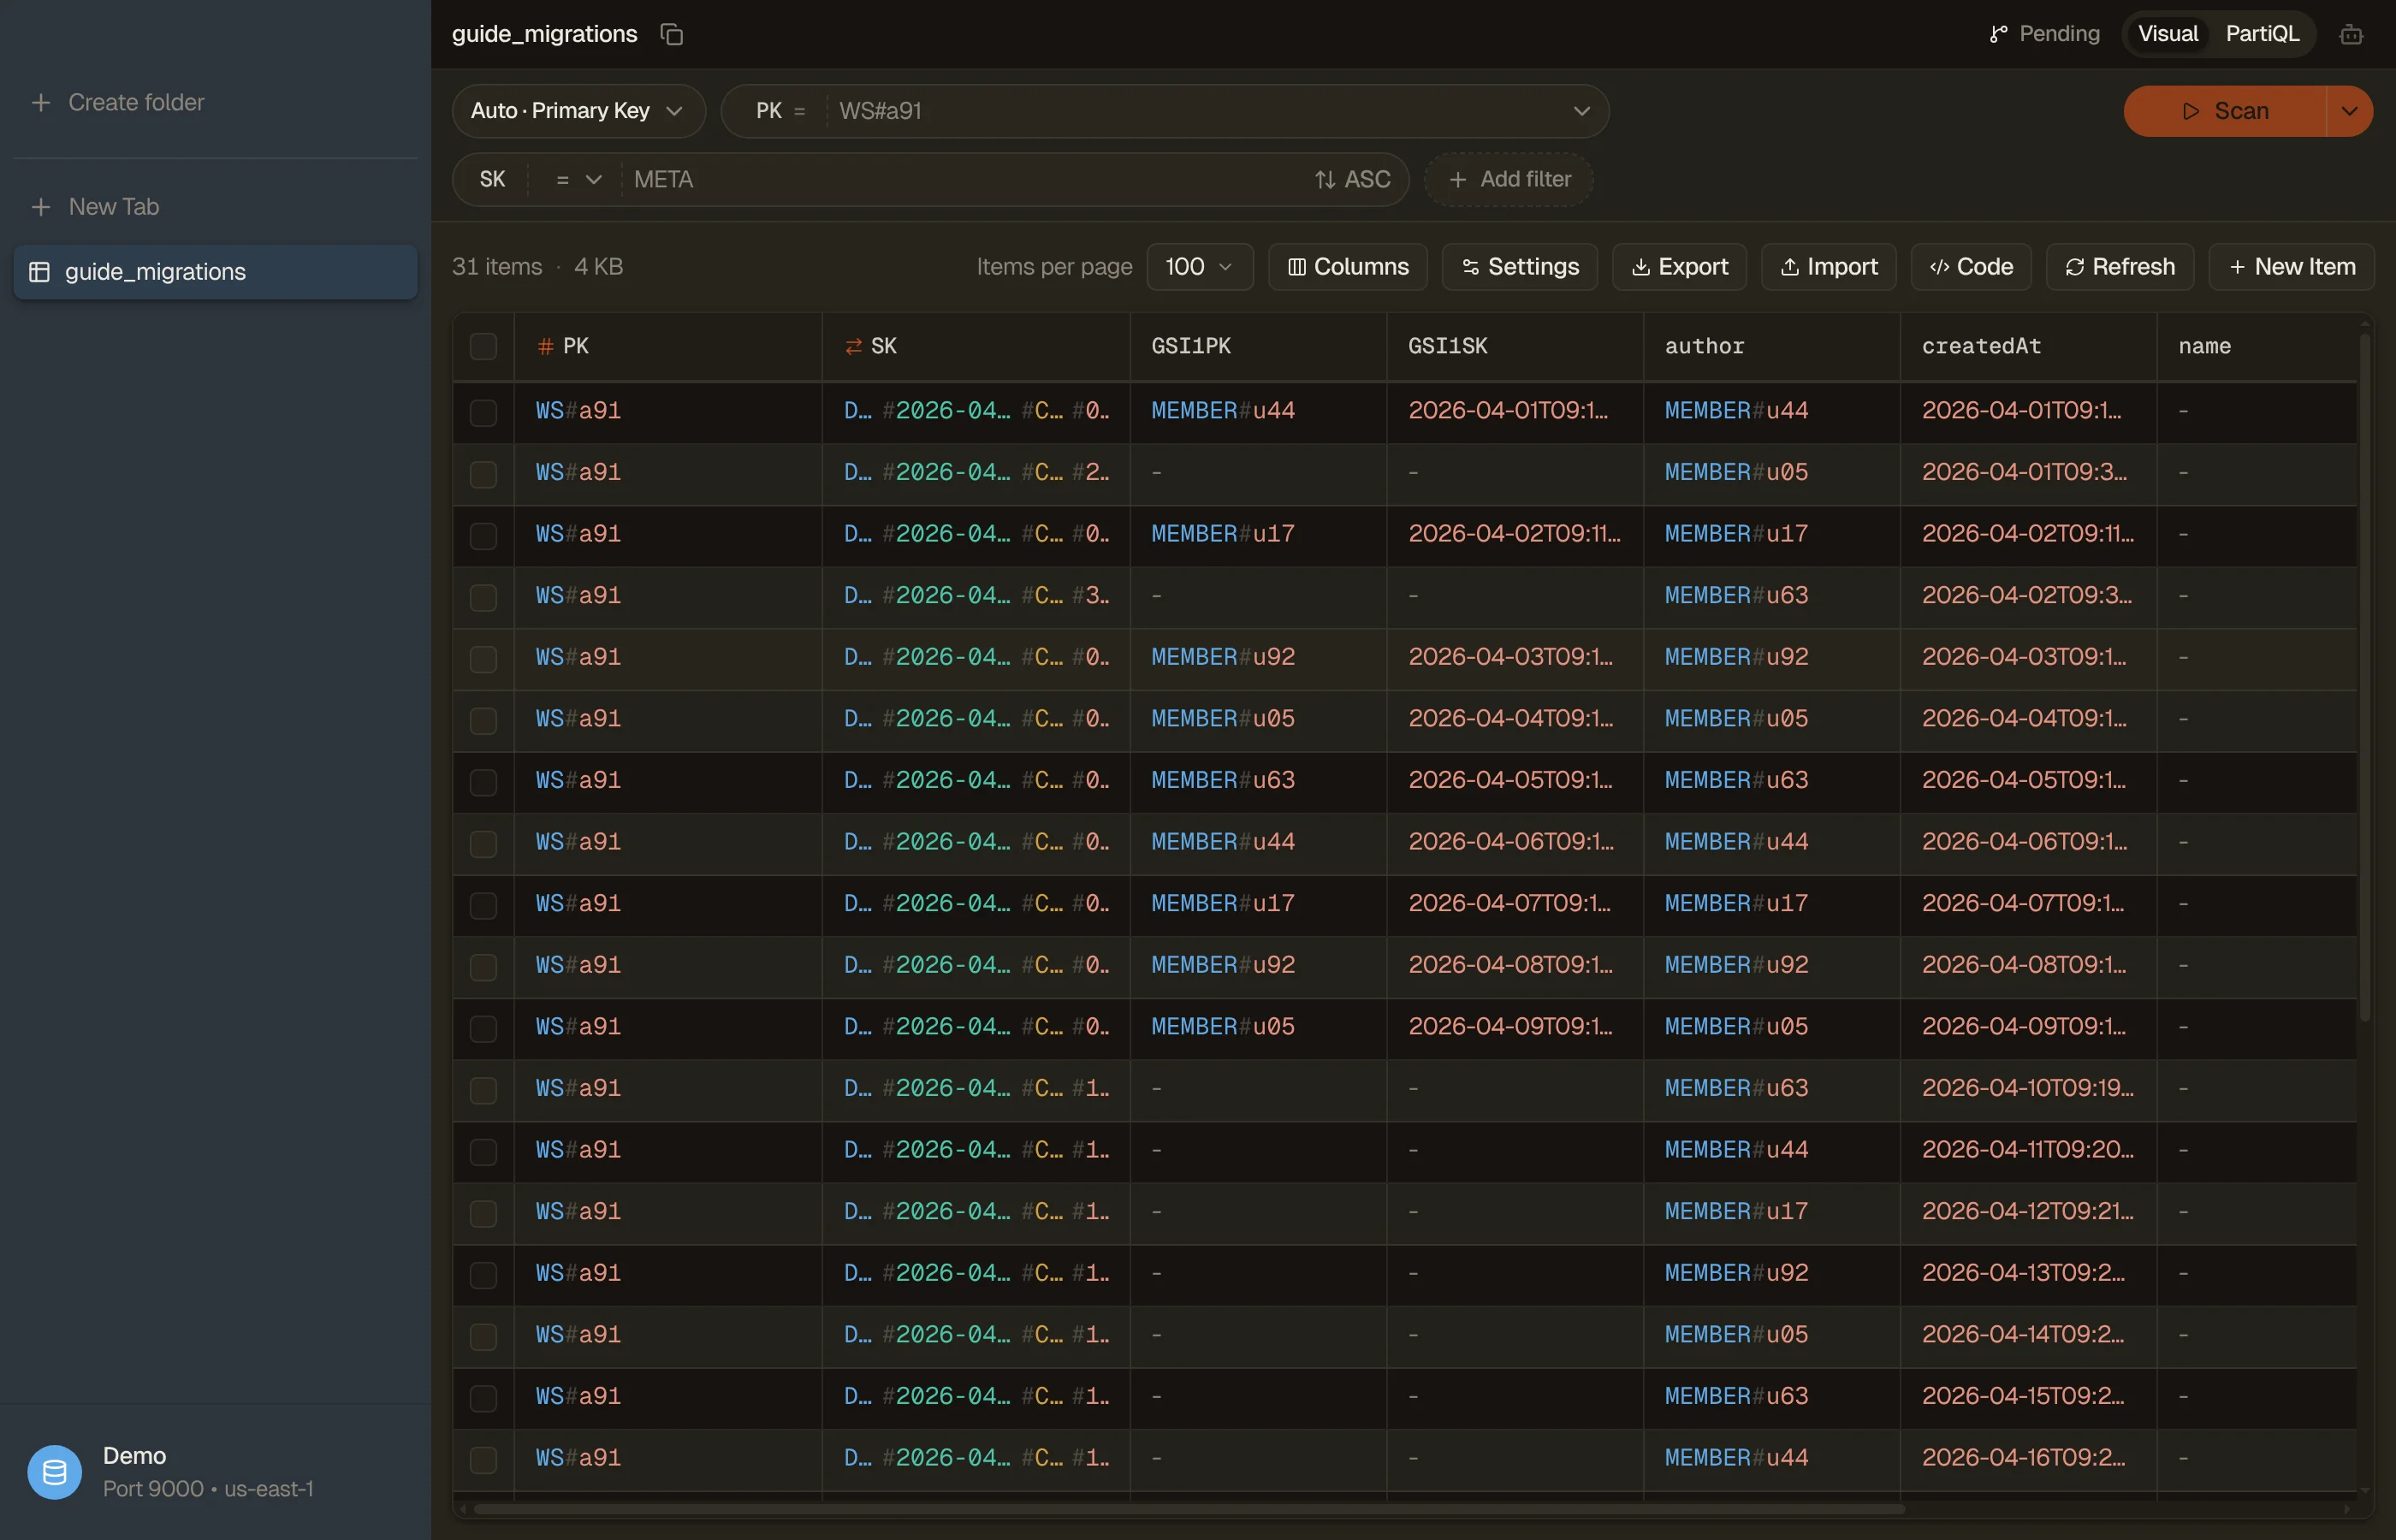
Try DynoTable to create the GSI and watch it go from Creating to
Backfilling to Active, filter for comments where GSI1PK is Attribute Not
Exists, and fix stragglers one by one, each commit guarded by a condition.