One-to-Many Relationships in DynamoDB
A SaaS control plane almost always has a containment hierarchy: one workspace
owns many projects. In SQL you'd put a workspace_id foreign key on the
projects table and JOIN.
DynamoDB has no joins and no foreign keys. Done right, "load a workspace and every
project inside it" becomes a single Query instead of one read plus a follow-up scan.
How do you model a one-to-many relationship in DynamoDB?
Give the parent and all its children the same partition key so they share one item collection, then tell them apart with the sort key. The relationship lives in the key schema, and loading a parent plus every child is one Query.
- Model the reads, not the entities. The relationship exists to serve "list a workspace's projects", so shape the keys around that query.
- Encode the parent into the child's partition key. The workspace and all its projects get the same partition-key value.
- Then the list read is one
Query. Parent and children come back together, up to 1 MB per page;LastEvaluatedKeyfetches the next page. - Watch the hot partition. A very busy tenant concentrates its traffic on one key. Past what one key can absorb, shard it and query every shard.
The access pattern, first
DynamoDB modeling is access-pattern-first, not entity-first: the same discipline behind single-table design. Before choosing any key, write down the reads the app actually issues:
- Get one workspace's settings.
- List every project in a workspace, newest-first.
- Get one specific project by id, when you know its workspace.
The "one workspace, many projects" relationship only matters because of read #2. If you never listed a workspace's projects together, you'd store projects independently.
Why a bare foreign key won't do it
Every GetItem and Query targets a partition key. AWS's
Core Components
page says the partition-key value is the input to an internal hash function that
decides where data lives.
A plain workspace_id attribute on a project item isn't queryable until you index
it. You have two ways to make "a workspace's projects" one Query:
- Shared partition key (this guide): the project's partition key is the
workspace. One
Queryreturns the workspace record and its projects together. - A GSI on
workspace_id: projects keep their own partition key, and the index groups them by workspace. Pick it when projects are mostly read by their own id. The index is eventually consistent and bills its writes.
Worked example: workspaces and projects
Use a generic, overloaded key schema. Call the partition key EntityRef and the
sort key Detail. The workspace identity goes into EntityRef for both the
workspace item and every project under it:
| EntityRef | Detail | attributes |
|---|---|---|
| WS#acme | META | displayName, region, seatLimit |
| WS#acme | PROJ#2026-0007 | title, status, createdBy |
| WS#acme | PROJ#2026-0042 | title, status, createdBy |
| WS#acme | PROJ#2026-0118 | title, status, createdBy |
| WS#globex | META | displayName, region, seatLimit |
| WS#globex | PROJ#2026-0009 | title, status, createdBy |
The workspace and all its projects share EntityRef = "WS#acme", so they form a
single item collection, stored in Detail order.
META is the workspace record. Each project carries a PROJ# prefix and a
zero-padded, time-ordered id, so projects sort by creation.
DynamoDB has no auto-increment: take the next number from an
atomic counter on one global item (say
COUNTER#project), or use a time-sortable id such as a ULID.
Either way an id is unique across workspaces, which the bare-id lookup below relies on.
Size the zero-padding for the global counter, not one workspace: use eight or more digits, and check the width in the code that writes the key.
The examples use four digits to stay readable, which caps the counter at 9,999 projects:
the 10,000th, PROJ#2026-10000, sorts before PROJ#2026-9999, and newest-first breaks.
Now the three access patterns each collapse to one call:
- Workspace settings:
GetItem(EntityRef="WS#acme", Detail="META"). - List projects newest-first:
Query(EntityRef="WS#acme")withDetail begins_with "PROJ#", run in descending order (ScanIndexForward = false). - One project:
GetItem(EntityRef="WS#acme", Detail="PROJ#2026-0042").
The project list comes back from one Query with no second round trip, a page of
up to 1 MB at a time. The begins_with on a sort-key prefix is the
composite sort key technique in its simplest
form.
The DynamoDB Expression Builder generates the
KeyConditionExpression, the #name/:value placeholder maps, and a ready-to-run
SDK snippet for that begins_with read:
KeyConditionExpression     "#er = :er AND begins_with(#d, :p)"
ExpressionAttributeNames   { "#er": "EntityRef", "#d": "Detail" }
ExpressionAttributeValues  { ":er": "WS#acme", ":p": "PROJ#" }
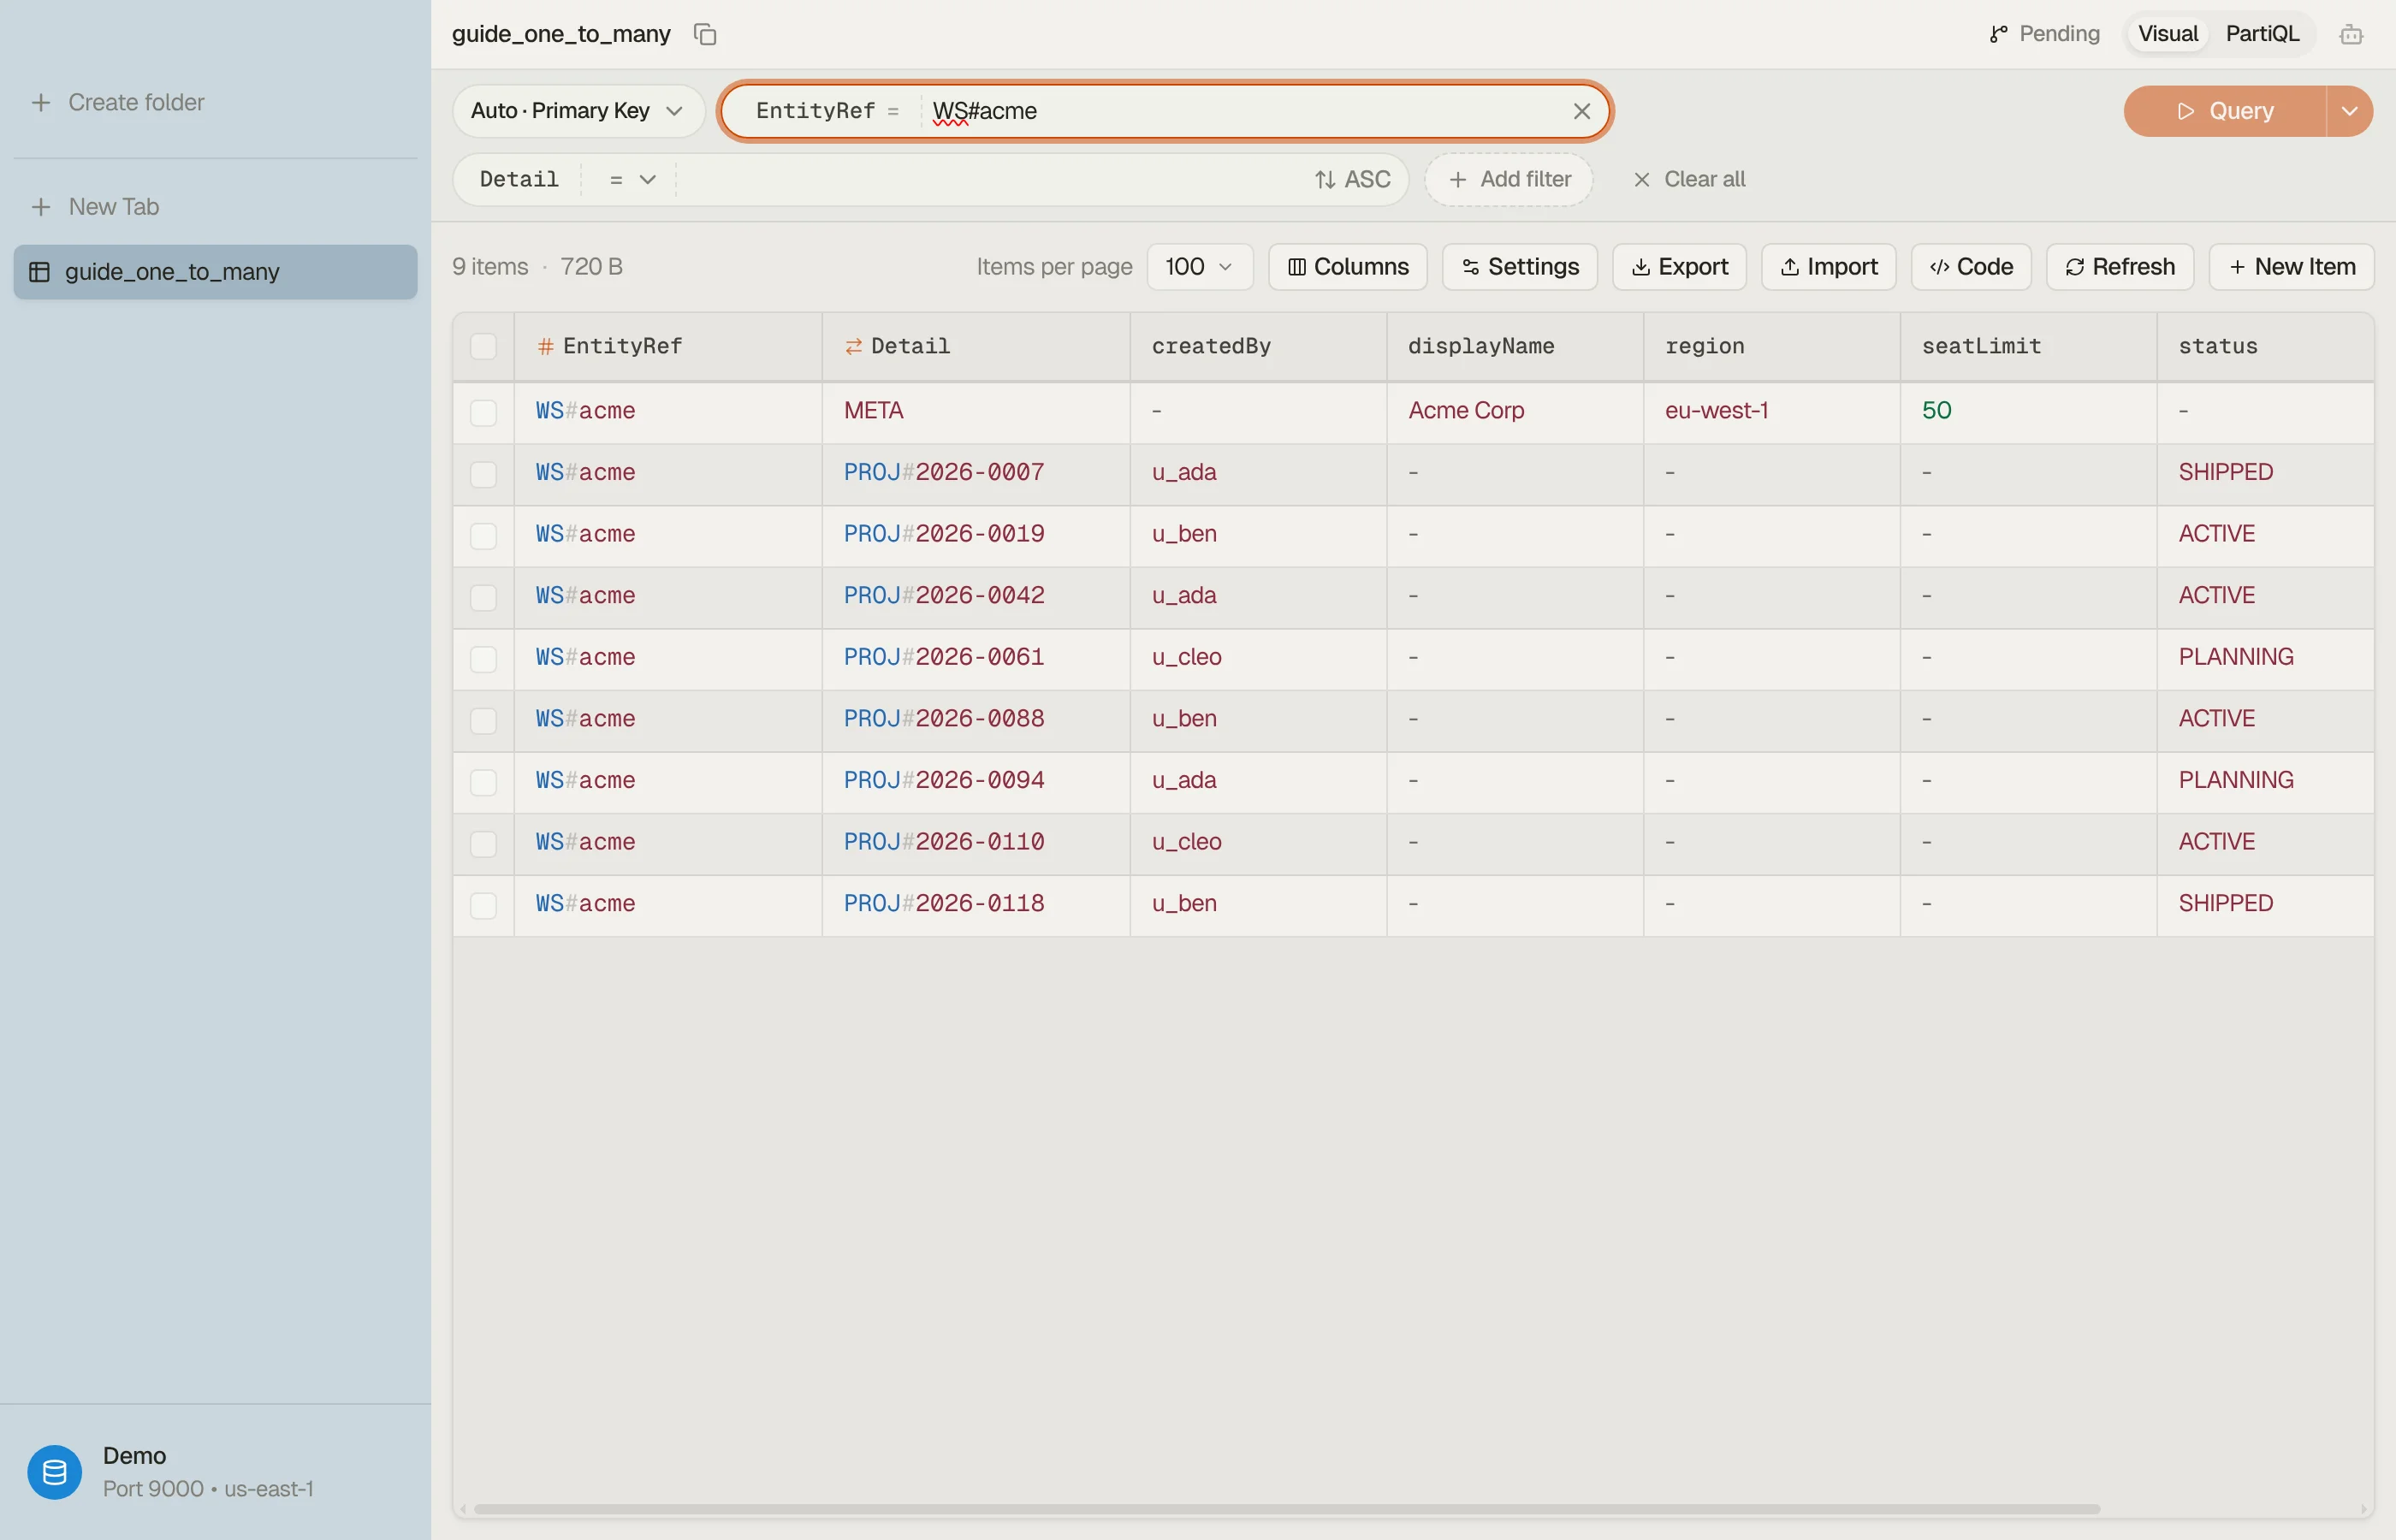
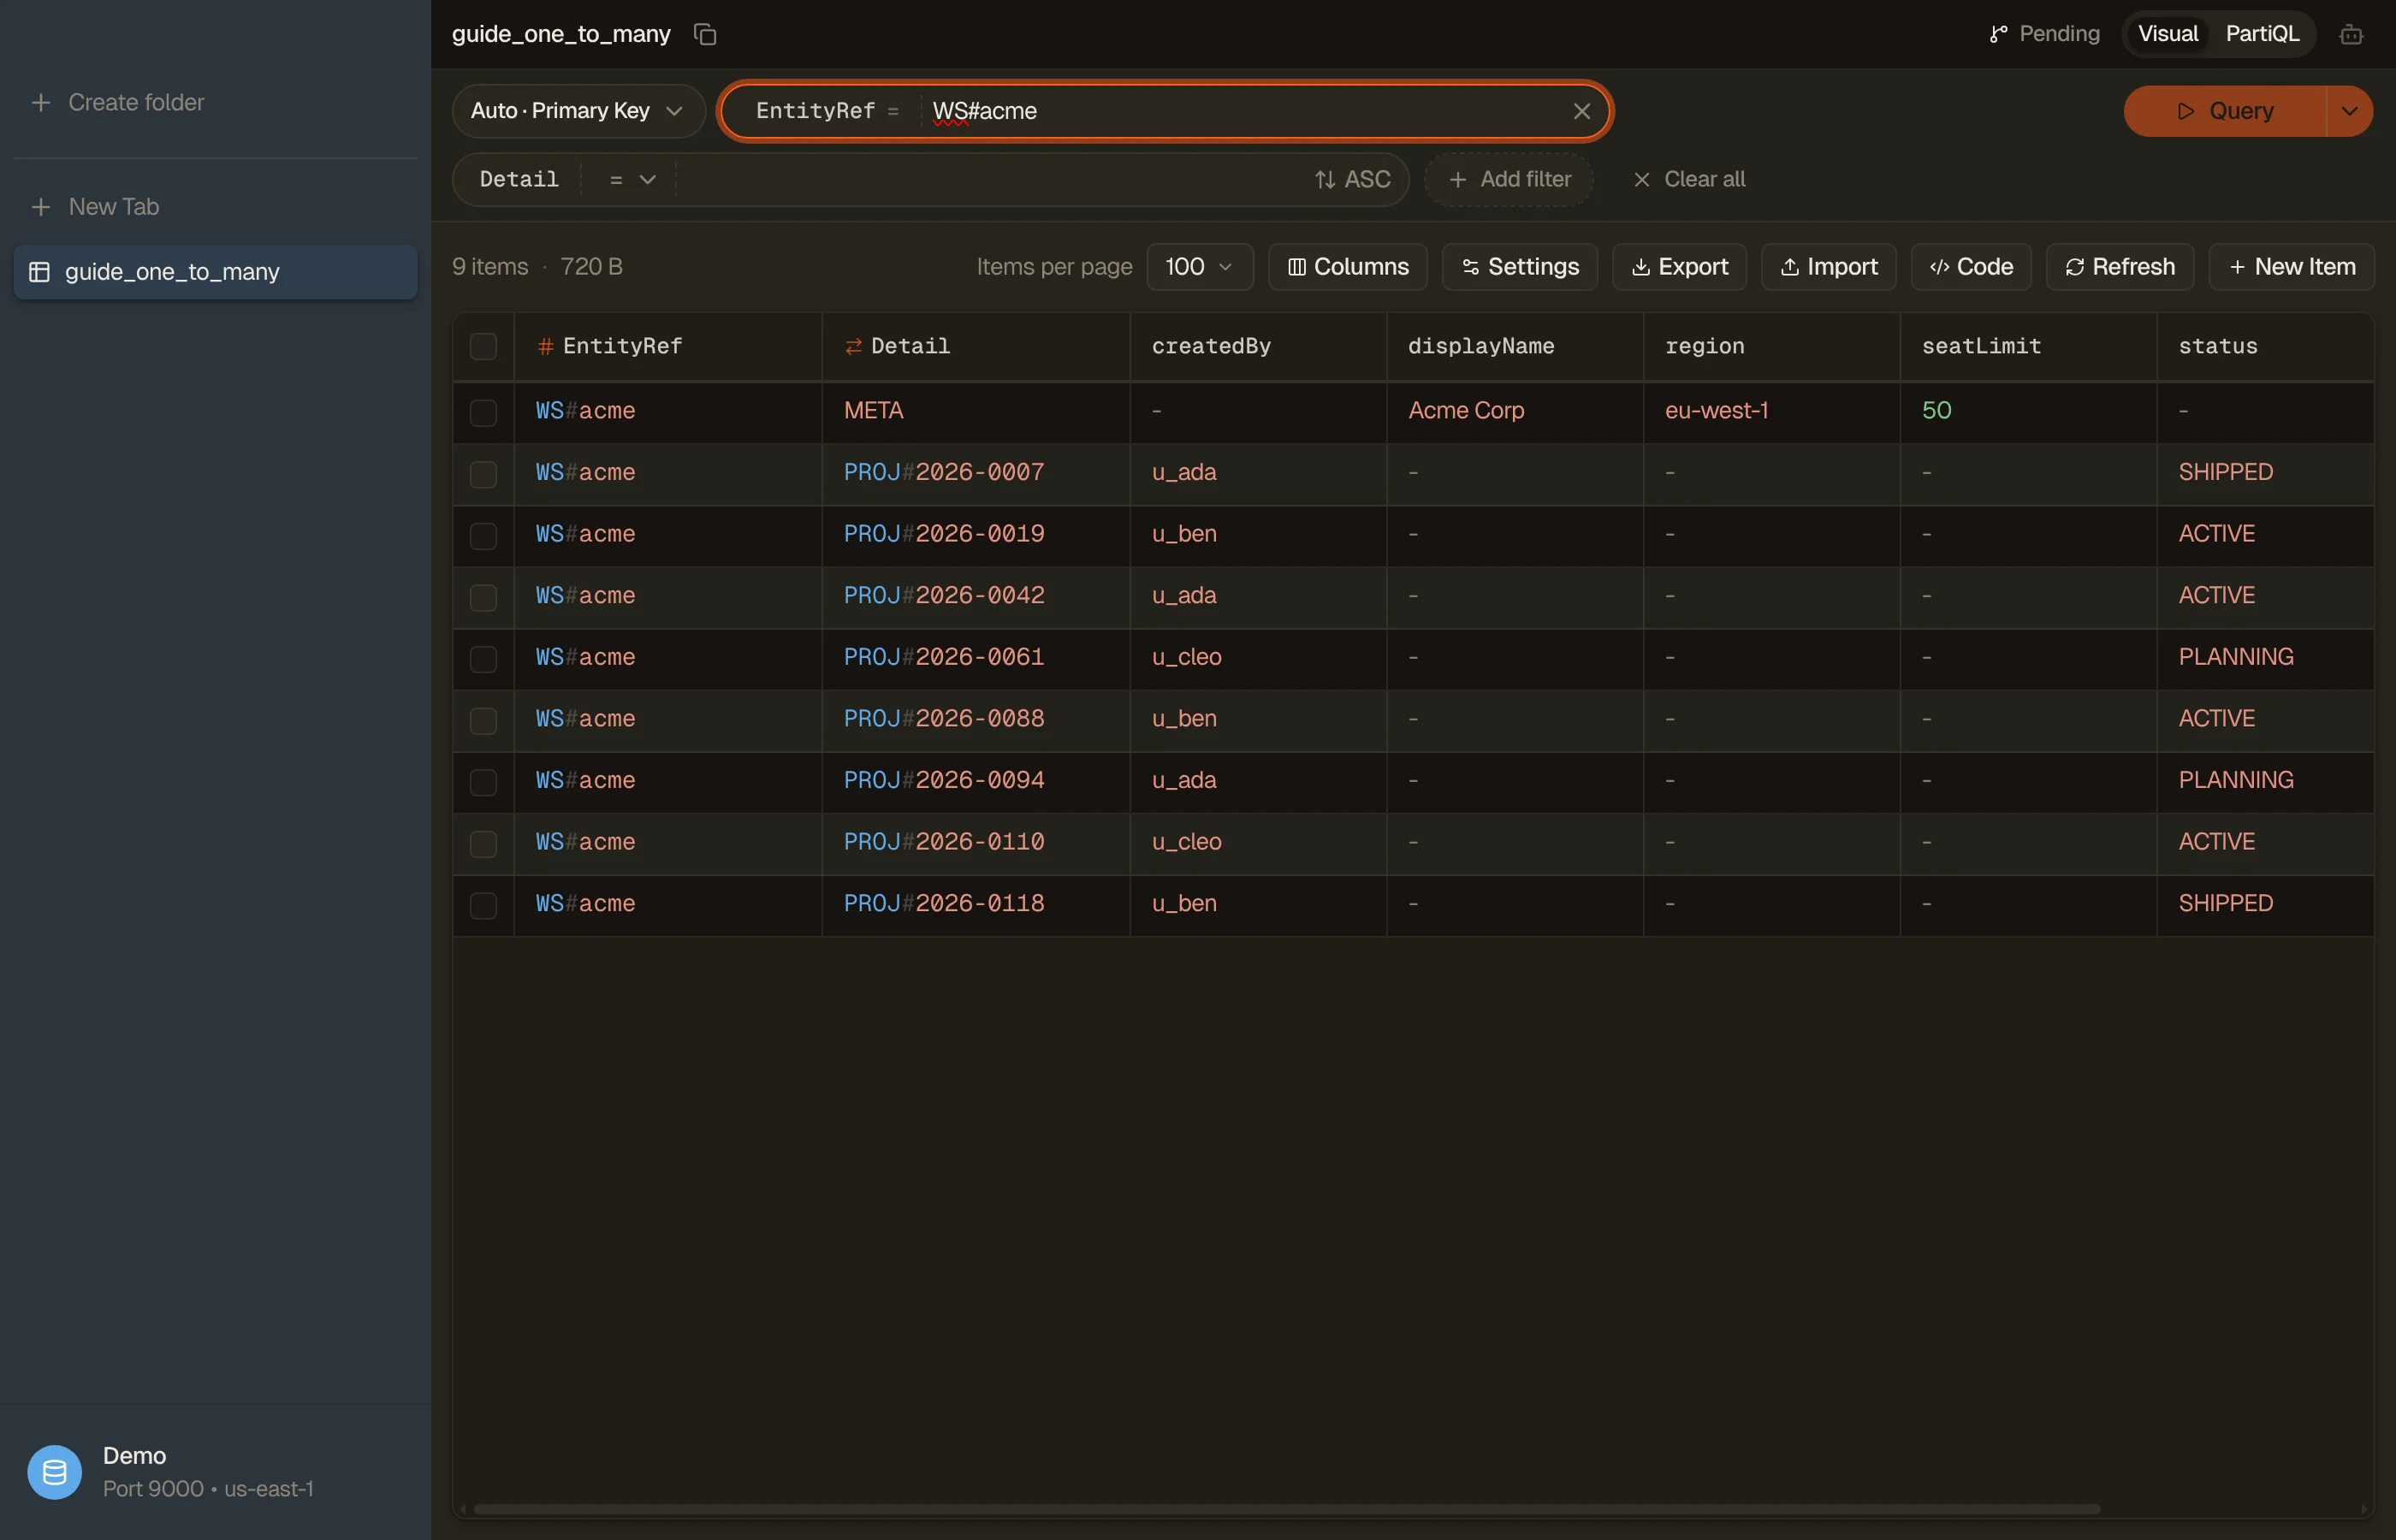
Inspect the item collection in DynoTable
Run a Query on EntityRef = WS#acme and the rows come back as one contiguous
block, META first and then each project in sort-key order. You see the one-to-many
relationship as one collection instead of guessing at it across separate tables.


Pitfalls and the alternative shapes
Hot partitions: one very busy tenant concentrates its traffic on one key. Size alone isn't the trigger.
Without an LSI, DynamoDB can split a busy collection by sort key, though not when traffic tracks a steadily increasing sort key, as new time-ordered ids do (how splits work).
If sustained writes still throttle, shard the key (WS#acme#0 … #9) and read with
one Query per shard, merged newest-first in your code.
Derive the suffix from the project id (a hash mod 10), so one project stays a
GetItem, and keep META on the unsharded key.
Hot partitions covers both halves.
Item-collection size: with a local secondary index, one partition-key value's item collection is capped at 10 GB; without an LSI there's no such limit. If a workspace can outgrow that, use a GSI instead of an LSI.
If you keep the LSI, set ReturnItemCollectionMetrics = SIZE on writes and alert
well below 10 GB (AWS suggests 8 GB). Item collections
covers the limits.
Reach for Query, never Scan: the whole design exists so you can Query one
partition. A filtered Scan to "find a workspace's projects" reads the entire table,
the trap covered in Query vs Scan.
A project id without its workspace: a deep link or webhook that carries only
2026-0042 has no key to read. Store a projectId attribute on each project and
index it in a GSI; with globally unique ids (above), the lookup returns one project.
If you number projects per workspace instead, 2026-0042 exists in many of them, so
make the public id embed the workspace (acme/2026-0042) and skip the GSI.
Listing across workspaces: "every ACTIVE project" can't come from the base
table, whose partition key is workspace-scoped.
Use a sparse index: write GSI1PK = ACTIVE and
GSI1SK = the project id only on active projects, and remove both when one closes.
The index then holds active projects and nothing else. If many writes hit that one
GSI1PK value, give it a shard suffix as above.
Next steps
Build and validate the key condition with the DynamoDB Expression Builder, and if you'd rather start from the access patterns themselves, the free Single-Table Design tool drafts the PK/SK/GSI plan with example items.
Then download DynoTable to create this table, query the
workspace→projects item collection, and see the parent and its children come back from
one Query.