DynamoDB Reference Counts
A reference count is a number you store on a parent item that tracks how many child items point at it: likes on a post, members in a workspace, replies on a comment. You keep it because counting the children on every read is too expensive.
How do you maintain a count in DynamoDB?
Store the running total on the parent item and update it in the same write that creates the child. A TransactWriteItems makes both land or neither, and a condition on the child stops a duplicate from counting twice.
- Don't count children at read time. A count
Querybills the bytes of every child it reads. Store the total on the post and read one item instead. - Bump the count in the write that creates the child, so the two never drift.
- Use a transaction when the child and the count are different
items.
TransactWriteItemsmakes both land or neither. - Guard the child write with a condition. Without it, a duplicate like re-runs the increment and inflates the number.
Why count at all
Coming from SQL, you'd never store a like-count; you'd SELECT COUNT(*) FROM likes WHERE post_id = ? and let an index make it cheap. DynamoDB has no COUNT(*) that
skips reading items: Select: COUNT still bills every item it reads.
The like item below is about 40 bytes. A post with a million likes holds about 39 MB of them, so counting reads roughly 4,800 RCU eventually consistent, over some 38 paginated calls, every time someone asks "how many likes?".
So you denormalize: store the running total on the post itself. Reading the count
becomes a single GetItem. The cost is that you now own keeping it accurate.
Model the items
Two item types share a partition, so the post and its likes sit in one item collection:
| PK | SK | attributes |
|---|---|---|
| POST#a91f | META | likeTally (Number), body, authorId, createdAt |
| PK | SK | attributes |
|---|---|---|
| POST#a91f | LIKE#USER#7c20 | likedAt |
The likeTally attribute on the META item is the reference count. Each LIKE#
item is a child. Putting both under PK = "POST#a91f" means a single Query can
fetch the post and its likers together when you do want the list.
Bump the count atomically
DynamoDB increments a number with an ADD update expression, or
SET x = if_not_exists(x, :zero) + :n (a plain SET x = x + :n fails while the
attribute doesn't exist yet).
This is an atomic counter: DynamoDB applies the delta server-side, so concurrent increments don't clobber each other (AWS: atomic counters).
Liking a post is two writes to two items: create the LIKE# item, and add 1
to likeTally on META. If the like lands but the bump fails, the tally is wrong
forever. You need both or neither.
That's what TransactWriteItems guarantees: all-or-nothing across multiple items,
canceled as a whole if another request modifies one of them mid-flight
(AWS: pessimistic locking with transactions):
{
  "TransactItems": [
    {
      "Put": {
        "TableName": "Social",
        "Item": {
          "PK": {"S": "POST#a91f"},
          "SK": {"S": "LIKE#USER#7c20"},
          "likedAt": {"N": "1750636800"}
        },
        "ConditionExpression": "attribute_not_exists(SK)"
      }
    },
    {
      "Update": {
        "TableName": "Social",
        "Key": {
          "PK": {"S": "POST#a91f"},
          "SK": {"S": "META"}
        },
        "UpdateExpression": "ADD likeTally :one",
        "ExpressionAttributeValues": {":one": {"N": "1"}}
      }
    }
  ]
}The Put and the Update commit together. If either fails, neither is applied, and
DynamoDB returns a TransactionCanceledException.
Guard against double-counting
The transaction prevents a half-written like. The remaining bug is the same user
liking twice, or a client replaying the request: each replay adds another 1, and
likeTally drifts above the true count.
The ConditionExpression: attribute_not_exists(SK) on the Put is the guard. If that
user's LIKE# item already exists, the condition fails, the whole transaction is
canceled, and the ADD never runs. One like per user, enforced by the key.
A canceled duplicate still comes back as an error, which can be a like that already
landed. Check CancellationReasons: when the Put's entry has code
ConditionalCheckFailed, the user had already liked the post, so show it as liked.
For retries you issue yourself, pass the same ClientRequestToken on each attempt.
DynamoDB then returns success for a call that already landed, without applying it
twice, for 10 minutes
(AWS: transactions).
The JavaScript SDK v3 fills in a token when you don't, and reuses it on its own automatic retries.
Build and copy these update and condition expressions, with the right
ExpressionAttributeValues and attribute_not_exists guard, in the
DynamoDB Expression Builder rather than
hand-assembling the JSON.
Unlike with the mirror transaction
Removing a like is the mirror image: Delete the LIKE# item with
ConditionExpression: attribute_exists(SK), and ADD likeTally :minusOne in the same
transaction. The condition stops a double-unlike from driving the tally negative.
Know the price. A transactional write costs 2 WCUs per item up to 1 KB (one to prepare, one to commit) versus 1 WCU for a plain write.
A like touches two items, so it costs 4 WCU while META stays at or under 1 KB. A
canceled transaction is billed too.
UpdateItem bills the whole item, not the attribute it changed. With META at
3 KB in total (body, keys and all), each like costs 2 + 6 = 8 WCU. For large posts, keep the tally on its
own small item (SK = COUNT) and the cost stays at 4.
Gate a delete on the count
The same count can guard a delete. Say a workspace keeps projectCount on its META
item, bumped by the transaction that creates each project. Delete the workspace only
when nothing is left:
attribute_not_exists(projectCount) OR projectCount = :zeroThe first half matters. A workspace that never had a project has no projectCount
attribute, and projectCount = :zero alone evaluates false and refuses the delete.
Close the race from the other side too: give the Update that bumps projectCount a
condition attribute_exists(PK). A project added after the workspace was deleted then
cancels instead of re-creating META with a count of 1.
See it in DynoTable
To check one post, query its partition. The LIKE# rows come first and the META
row with likeTally sorts last (L before M). Compare the row count with the tally
on a post small enough to load; for a big one, use the recount below.

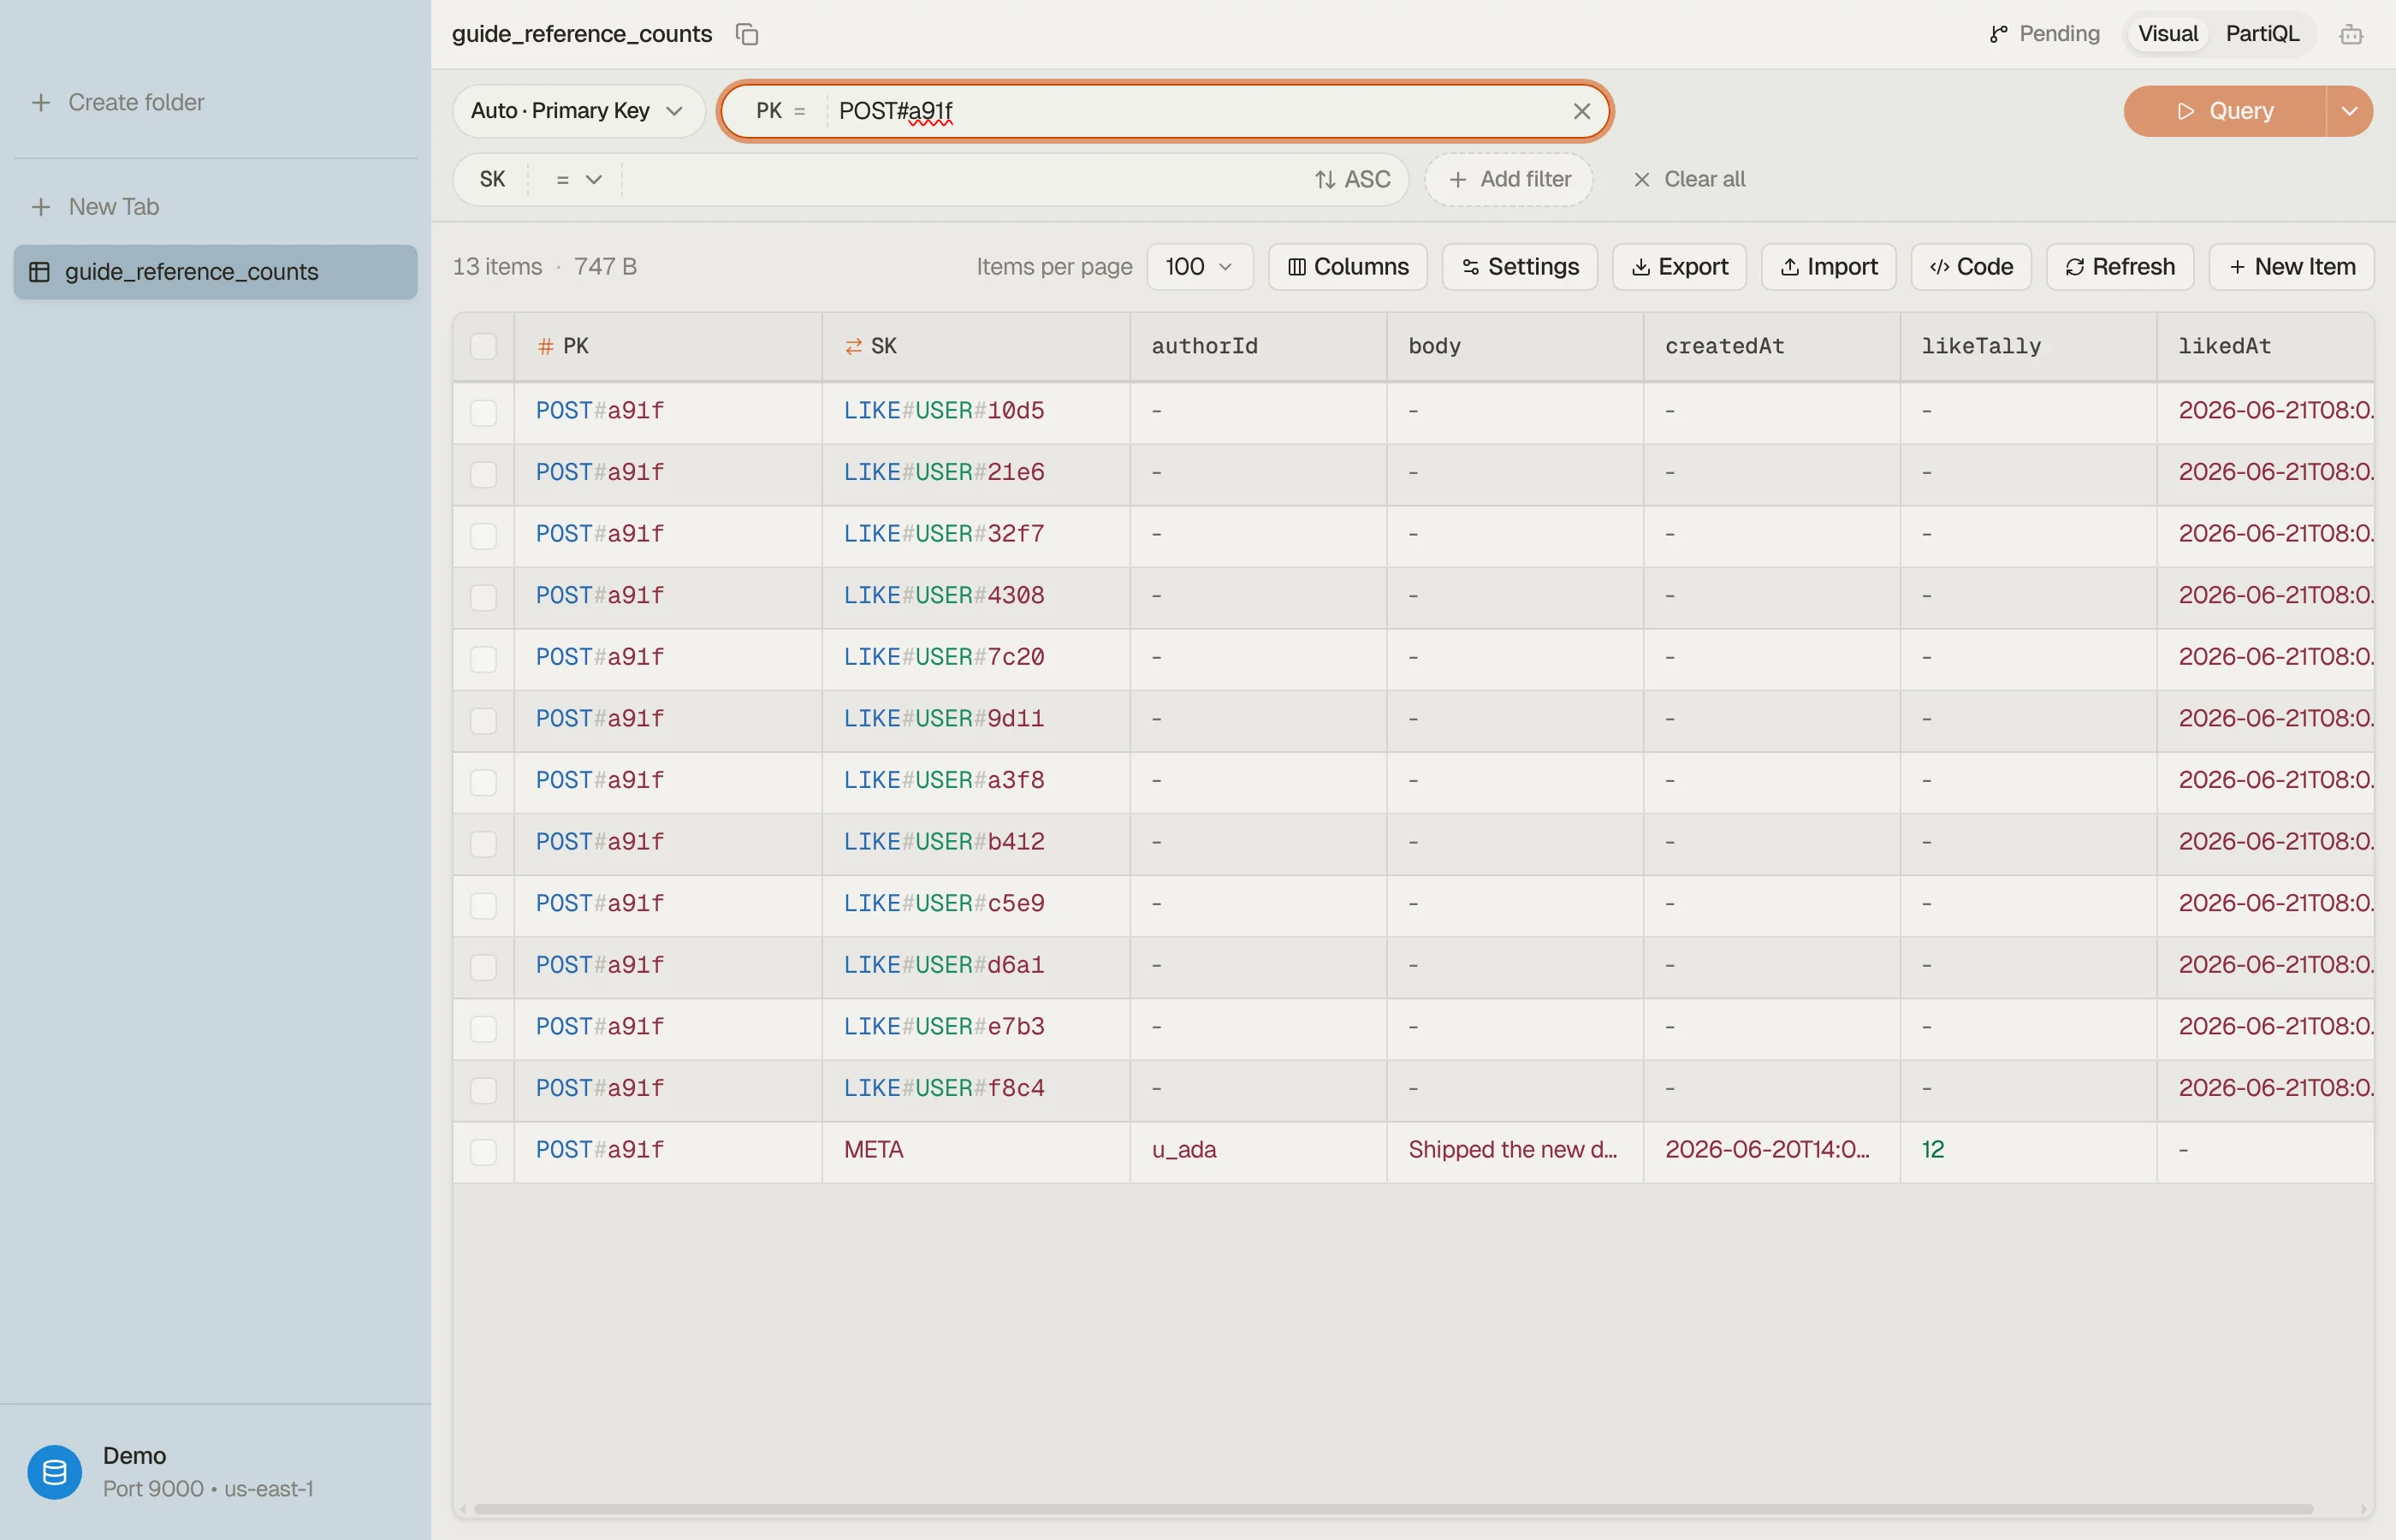

To compare a bounded set of posts at once, DynoTable's SQL Workbench needs no join.
One GROUP BY PK puts MAX(likeTally) beside
SUM(CASE WHEN SK LIKE 'LIKE#%' THEN 1 ELSE 0 END), which plain PartiQL can't express.
Use Run to end (⌘⇧↩) so every page is counted; a plain Run stops early and marks the aggregate partial.
Pitfalls and next steps
Hot posts: every like on one post updates the same META item. One item takes at
most 1,000 WCU a second, about 500 transactional likes a second.
Concurrent likes also conflict. A conflict cancels a transaction with
TransactionConflict, and the SDK doesn't retry it, so retry with jittered backoff.
Past that rate, shard the counter across partition keys: N items at
PK = "POST#a91f#<n>", SK = "COUNT". Bump a random one inside the like
transaction, and read all N with one BatchGetItem and sum.
Atomic counters and hot partitions cover the sharding.
Or take the bump out of the request: write only the LIKE# item, and let a
DynamoDB Streams consumer such as Lambda add batches of
likes to the tally. The count lags behind, which a like counter can usually afford.
Count an INSERT of a LIKE# item as +1 and its REMOVE (an unlike) as -1. Skip
every other record: creating or deleting the post is an INSERT or REMOVE of META,
and the consumer's own ADD comes back as a MODIFY of META.
Lambda retries a failed batch, so report the first failed record
(ReportBatchItemFailures) to resume there instead of re-adding the whole batch. The
recount below repairs any drift, with one extra check on this path.
A nightly recount is not a write path. A job that recounts every post papers over a write path that should have been transactional. Stream aggregation is different, because it is the write path itself.
Reconcile rarely, then repair. Drift should be near zero if every mutation is conditioned, so a mismatch points at a write path to fix first.
Then recount with
Query PK = "POST#a91f" AND begins_with(SK, "LIKE#"), Select: COUNT,
ConsistentRead: true, summing Count across pages.
Write the result with SET likeTally = :n and a condition likeTally = :old, the
value you read before counting. A like that lands mid-repair makes the condition fail
instead of being lost; recount and try again.
With stream aggregation, the tally trails the likes still in the stream, and the recount counts them. Repair then, and the consumer adds them again on top: on DynamoDB Local, 3 likes ended at a tally of 6.
So read the tally, count, wait longer than the consumer's lag (its IteratorAge
metric), and read the tally again. If it moved, likes were still in flight or new ones arrived; retry when the post is quieter (off-peak, or once it cools).
If it didn't move, everything the count saw was already applied. Write that count, conditioned on the first tally; likes that land afterwards add on top correctly.
Related reading: single-table design for why the post and likes share a partition, and Query vs Scan for why counting children at read time is the pattern you're avoiding.
Then download DynoTable to inspect these item collections and verify your tallies against your own tables.