DynamoDB Item Collections
An item collection is the set of all items in a table (or index) that share the same partition key value. Nobody declares it; it falls out of your key schema.
The moment two items carry the same partition key, they form a collection, and
DynamoDB lets you read a collection together in one Query. Get it right and
related items come back in one round trip; get it wrong and you're stuck with a Scan.
What is a DynamoDB item collection?
- A collection is "same partition key." Items with the same partition key value are stored together, sorted by sort key.
- It's the unit of one
Query.Queryreads within one collection;Scanwalks every partition. - It can mix item types. A parent item and its children can share the key, so one
Queryreturns the profile and its history together. - One hard limit, only with an LSI: a collection on a table with an LSI is capped at 10 GB. Without an LSI, DynamoDB can split a collection across partitions.
The problem: reading related items together
Say you run a fleet of vehicles, each streaming telemetry (speed, coolant
temperature, fuel level) every few seconds. The dominant read is "give me the
vehicle's profile and its recent readings" for vehicle V-7741.
Coming from SQL, you'd index a vehicle_id column and let the planner do the work.
A plain key-value store treats every reading as an isolated record, so the same
question means a filtered scan of the whole table, costlier as the fleet grows.
DynamoDB's answer is to make "everything about one vehicle" a physically grouped, directly addressable thing. That grouping is the item collection.
How DynamoDB stores a collection
DynamoDB routes each item to a partition by hashing its partition key, and stores items with the same partition key together, sorted by sort key. AWS names that group an item collection.
A collection starts on one partition. Without an LSI, DynamoDB splits one that grows large or hot across as many partitions as it needs (AWS docs). An LSI pins the collection to one partition, hence the 10 GB cap below.
Because the collection is sorted, a Query reads a contiguous range of it and bills
only the items it reads.
To form a collection you need a composite primary key: a partition key and a sort key. A table keyed on partition key alone has one item per key value, so there's nothing to collect. The composite primary key guide covers choosing that key.
Our worked example: vehicle → telemetry readings
Model the telemetry stream with a composite key. The partition key identifies the
vehicle; the sort key is META for the profile and the timestamp for each reading.
Readings sort oldest first; pass ScanIndexForward=false for newest first.
| PK (vehicleId) | SK (recordedAt) | attributes |
|---|---|---|
| VEH#V-7741 | META | plate, model, depotCode |
| VEH#V-7741 | TS#2026-06-23T09:00:01Z | speedKph, coolantC, fuelPct, depotCode |
| VEH#V-7741 | TS#2026-06-23T09:00:06Z | speedKph, coolantC, fuelPct, depotCode |
| VEH#V-7741 | TS#2026-06-23T09:00:11Z | speedKph, coolantC, fuelPct, depotCode |
| VEH#V-7742 | META | plate, model, depotCode |
| VEH#V-7742 | TS#2026-06-23T09:00:02Z | speedKph, coolantC, fuelPct, depotCode |
Two collections live here, one per vehicle. The META item and all of V-7741's
readings form one collection; V-7742's items form another. Each reading also
records its vehicle's depot, which the index section below relies on.
META sorts before any TS#... value, so a single Query on
PK = "VEH#V-7741" returns the vehicle's profile and its readings together.
That's the parent-and-children pattern at the heart of
single-table design.
Each box is one item collection: same partition key, items sorted by sort key.
A Query reads exactly one box.
Querying a collection
Because a collection can hold more than one item type, the sort-key condition is how you pick which ones come back. To read only the readings, newest first:
# Query
KeyConditionExpression   vehicleId = :v AND begins_with(recordedAt, :ts)   # :ts = "TS#"
ScanIndexForward         false        # newest first
Drop the sort-key condition and the same Query returns the profile plus every
reading; recordedAt = "META" fetches just the profile. Time windows (BETWEEN on a
sortable timestamp) and paging past 1 MB are covered in the
composite primary key guide.
Building these key conditions by hand is fiddly. The
DynamoDB Expression Builder generates the
KeyConditionExpression, ExpressionAttributeNames and ExpressionAttributeValues,
so reserved words and placeholders don't bite.
Collections on indexes
A secondary index has its own key schema, so it forms its own item collections.
Because every reading carries depotCode, a global secondary index keyed on
depotCode (partition) and recordedAt (sort) gathers all readings from depot
DEP-LON-3 into one index collection, a read the base table can't serve.
Query it with depotCode = :d AND begins_with(recordedAt, :ts) and
ScanIndexForward=false for newest first. Items without depotCode never enter the
index, so copying it onto each reading is what makes this read work
(sparse indexes).
That's why the index type matters: it governs what collections you can form and how they behave. See GSI vs LSI for the trade-off.
A local secondary index (LSI) shares the base table's partition key, so its entries live in the same collection as the base items, and that creates the hard limit below.
The limits that bite
Two constraints decide how you shape keys:
The 10 GB LSI limit. On a table with a local secondary index, one item collection (base items plus LSI entries for one partition key) can't exceed 10 GB; writes that would grow it fail with
ItemCollectionSizeLimitExceededException.A table with no LSI has no such cap.
To see it coming, set
ReturnItemCollectionMetrics: "SIZE"on writes and alarm when a collection's estimate passes about 8 GB, as the LSI docs suggest.At the limit, delete items you no longer need from that collection, or move history to a new table or to S3. An LSI lives as long as its table, so append-only telemetry belongs on a GSI or a time-bucketed partition key from the start.
Hot keys. A split can't spread one item or the leading edge of an ever-increasing sort key such as
TS#…, so a hot vehicle or depot needs write sharding; hot partitions covers how.
See it in DynoTable
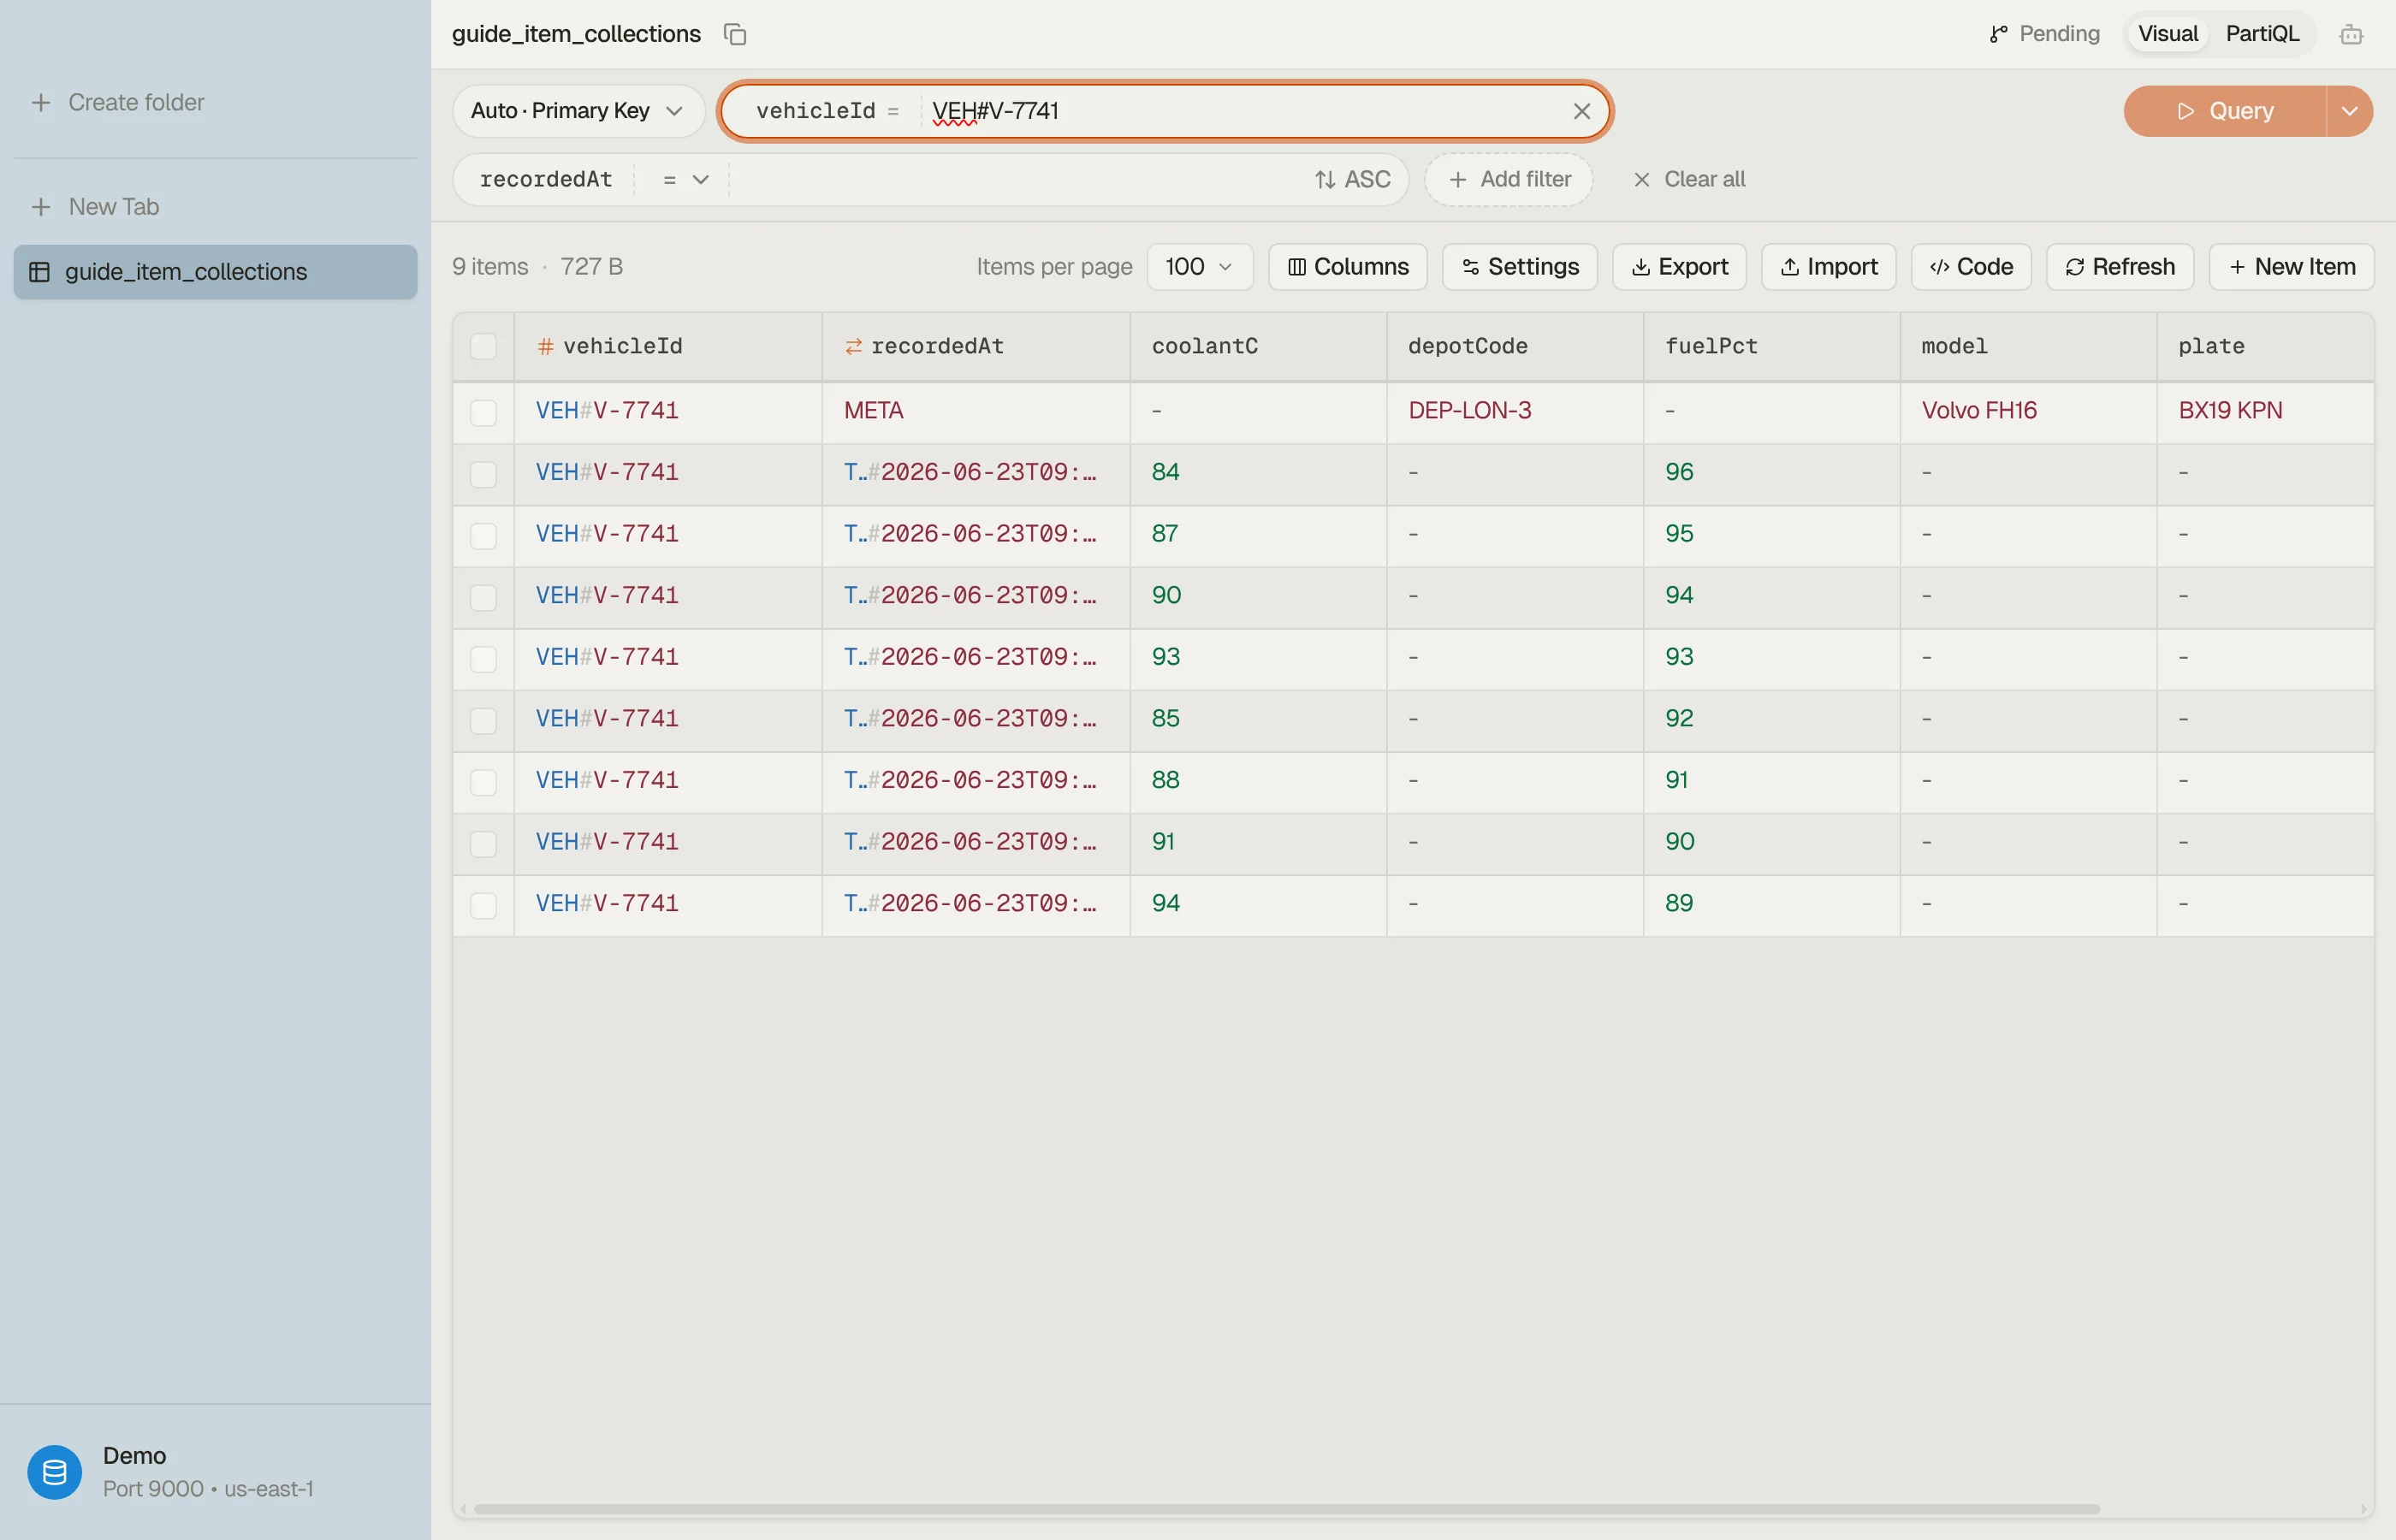
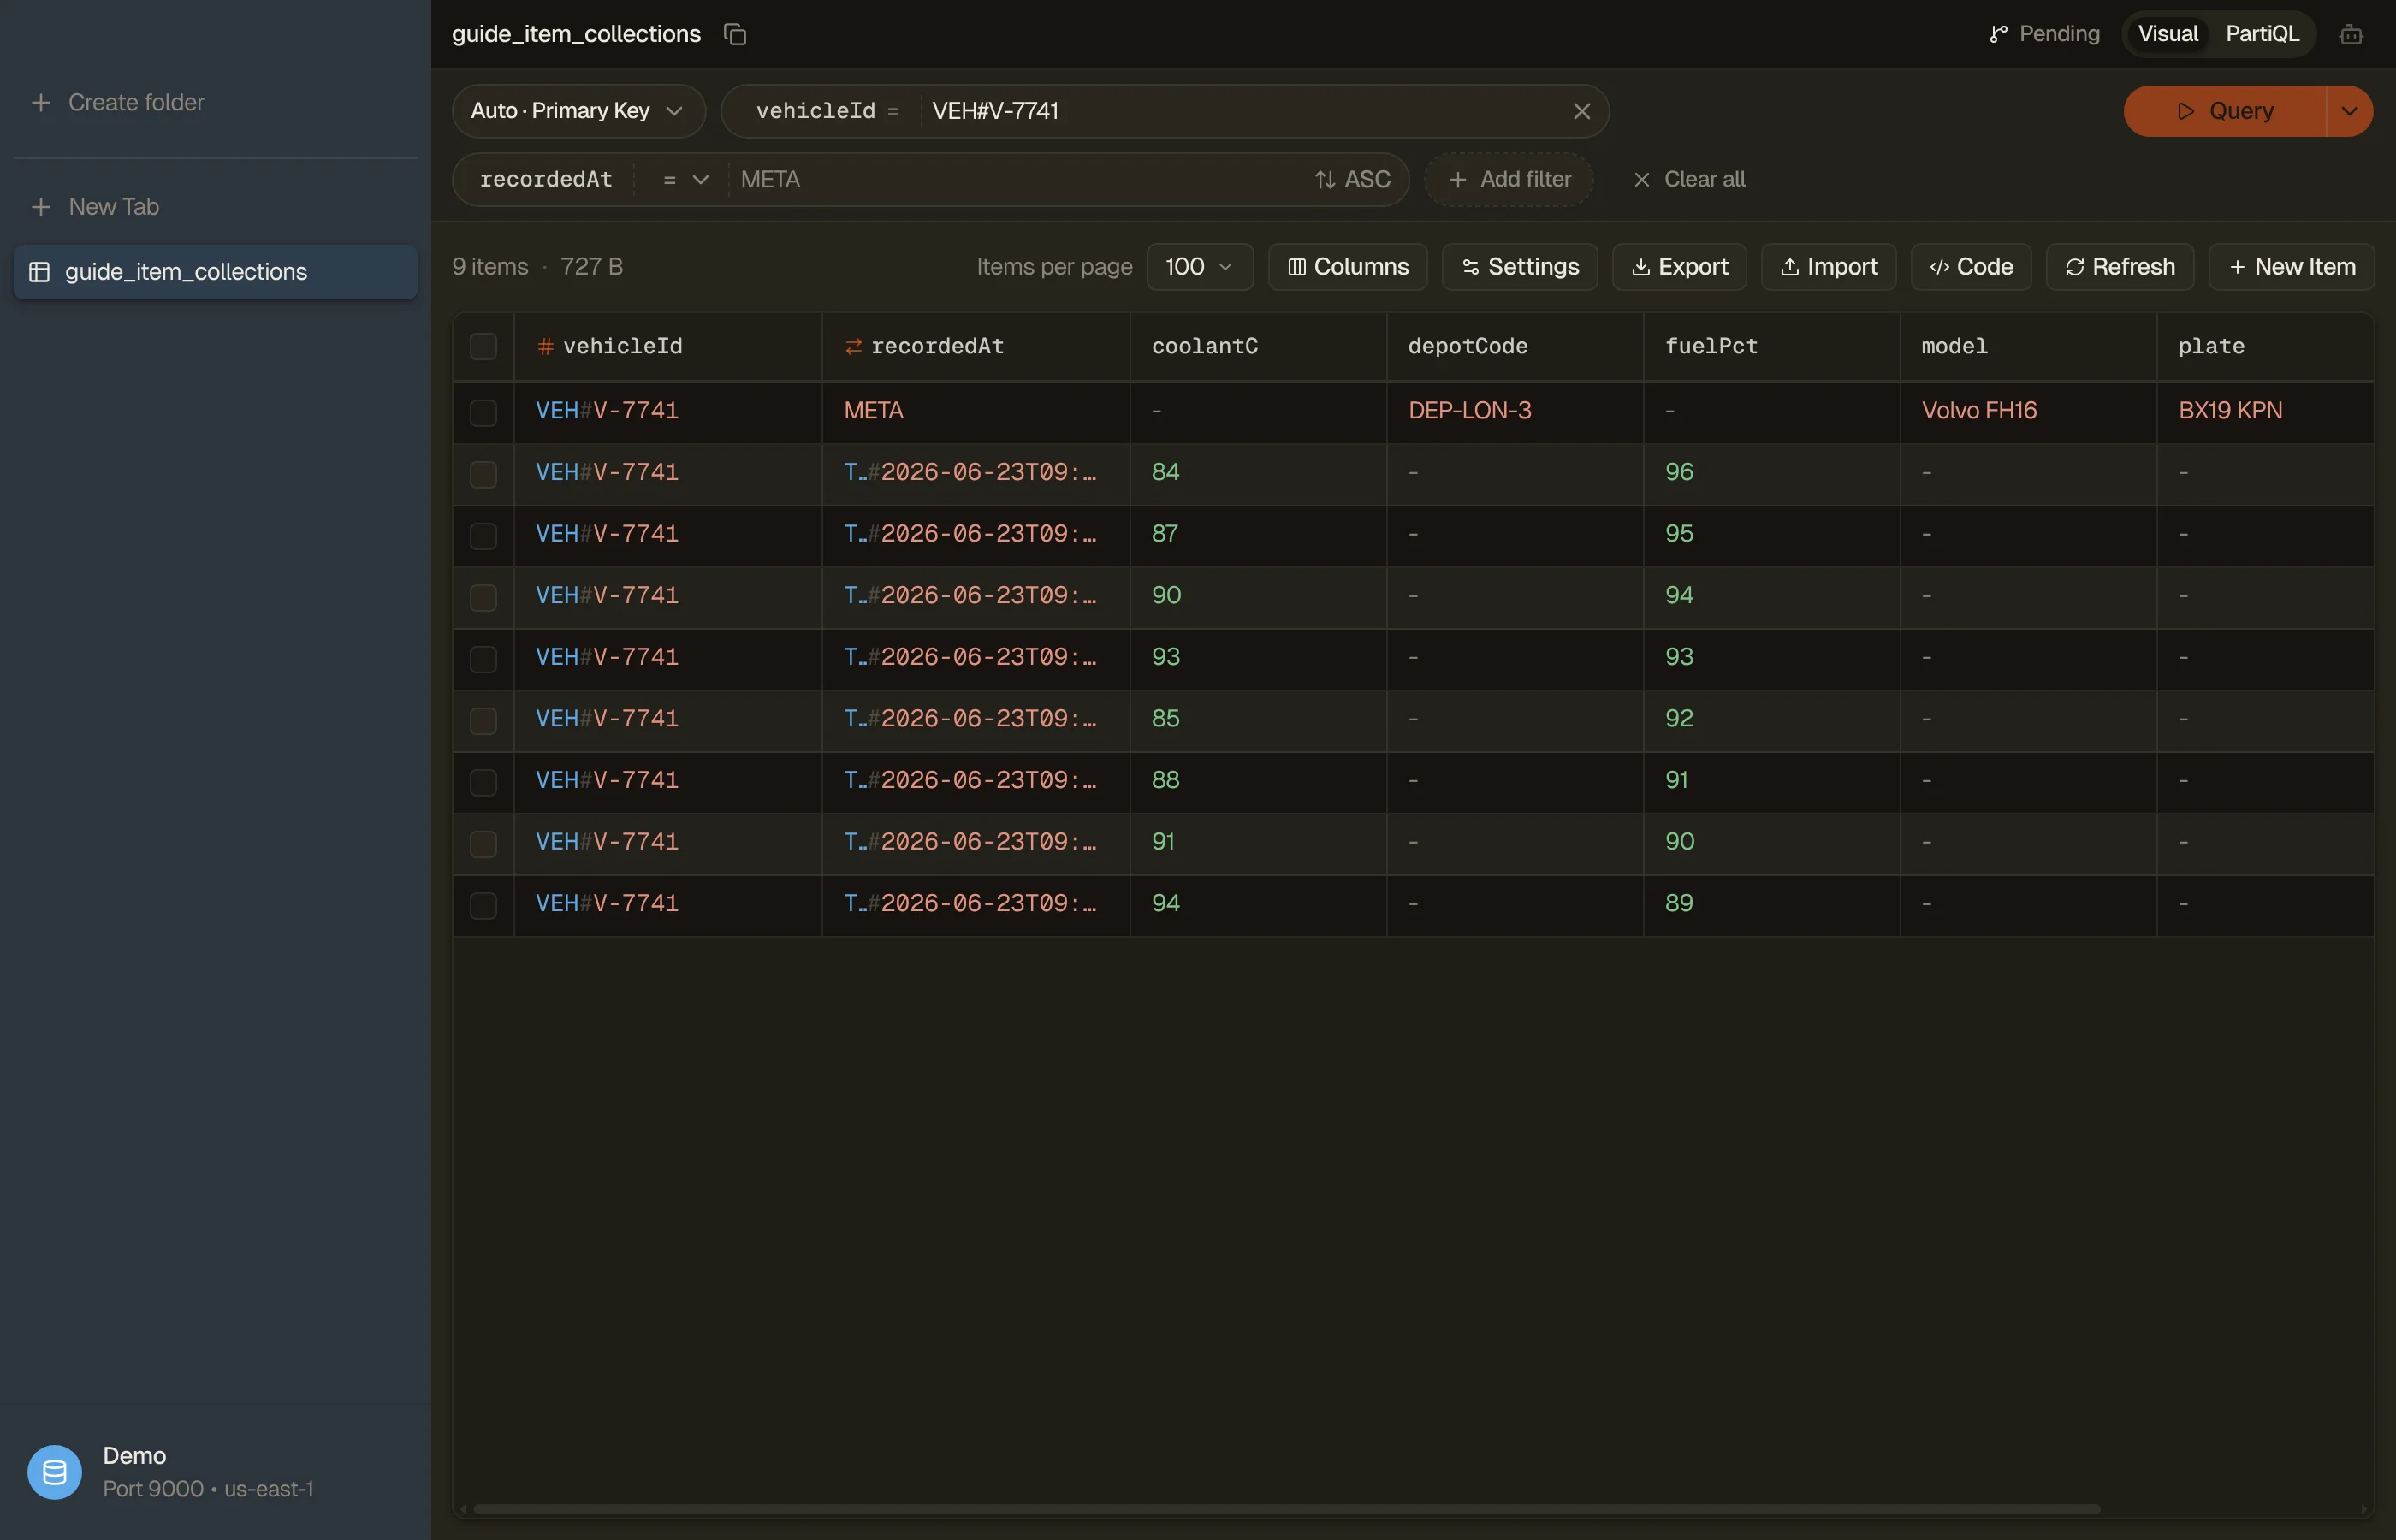
The fastest way to build intuition for collections is to look at one. In DynoTable,
a Query on one partition key lists the collection in sort-key order: the META
item sits right ahead of its timestamped readings, on screen.


Pitfalls and next steps
- No sort key, no collection. A partition-key-only table can't group items, and its key schema can't change. Add a GSI keyed on the grouping attribute plus a sort attribute, or move to a new table (migrations).
- Don't let an LSI collection grow unbounded. Append-only streams belong on a GSI (or a time-bucketed partition key), not an LSI, because of the 10 GB ceiling.
- Spread your partition keys. Low-cardinality keys pile traffic onto a few collections; physical partitions explains the per-partition limits.
- Reach for
Query, notScan. Collections exist so you can read related items with one targetedQuery; see Query vs Scan.
Sketch your own key schema, run a Query against a real partition key, and watch the
collection come back ordered. Download DynoTable and explore your tables'
collections directly.